
Vector Graph RAG
Graph RAG with pure vector search — no graph database needed, configurable model reranking, optimized for knowledge-intensive domains.
Use the default model or enable the two-stage Jev reranker. The evaluation includes the Luna/Flash comparison and measured model-call timings.
Why Vector Graph RAG?
Most Graph RAG systems require a dedicated graph database (Neo4j, etc.) and complex multi-step retrieval with iterative LLM calls. Vector Graph RAG takes a fundamentally different approach:
flowchart LR
    subgraph Traditional["Traditional Graph RAG"]
        direction LR
        A1[Documents] --> B1[Graph DB\nNeo4j]
        B1 --> C1[Cypher\nQueries]
        C1 --> D1[Iterative\nLLM Calls]
        D1 --> E1[Answer]
    end

    subgraph VectorGraphRAG["Vector Graph RAG"]
        direction LR
        A2[Documents] --> B2[Milvus\nVectors]
        B2 --> C2[Vector\nSearch]
        C2 --> D2[Single LLM\nRerank]
        D2 --> E2[Answer]
    end
Key Advantages
- No graph database — The entire knowledge graph lives in Milvus as vectors. No extra infrastructure, no schema management, no graph query language.
- Single-pass reranking — Unlike agentic approaches (IRCoT, multi-step reflection), we call the LLM just once to rerank candidate relations. Simpler, faster, and cheaper.
- Knowledge-intensive friendly — Designed for domains where dense factual knowledge matters: legal documents, financial reports, medical literature, novels, and more.
Features
No Graph Database
Pure vector search with Milvus — no Neo4j, no ArangoDB, no extra infrastructure to deploy or manage.
Configurable Reranking
Choose single-pass generative reranking or two-stage Jev scoring, without an iterative search loop.
Multi-Hop Reasoning
Subgraph expansion discovers connections across documents for complex multi-hop questions.
Zero Configuration
Milvus Lite by default — works as a local file, no server setup needed. Just pip install and go.
State-of-the-Art
Two-stage Jev leads the compared baselines on MuSiQue and 2Wiki and reaches the quality–latency Pareto frontier. See the latest results.
Visual Explorer
Interactive frontend with step-by-step retrieval visualization showing how the algorithm reasons.
How It Works
flowchart LR
    Q[Question] --> EE["Entity\nExtraction"]
    EE --> VS["Vector Search\n(Milvus)"]
    VS --> SE["Subgraph\nExpansion"]
    SE --> LR["LLM Rerank\n(single pass)"]
    LR --> AG["Answer\nGeneration"]

    style VS fill:#e3f2fd,stroke:#1565c0
    style SE fill:#e3f2fd,stroke:#1565c0
    style LR fill:#fff3e0,stroke:#e65100
    style AG fill:#e8f5e9,stroke:#2e7d32
1 Extract entities from the question 2 Vector search finds similar entities and relations in Milvus 3 Subgraph expansion traverses the graph to discover multi-hop connections 4 LLM reranking selects the most relevant relations (single pass) 5 Generate answer from the selected context
Quick Example
from vector_graph_rag import VectorGraphRAG

rag = VectorGraphRAG()  # reads OPENAI_API_KEY from environment

rag.rebuild_texts([
    "Albert Einstein developed the theory of relativity.",
    "The theory of relativity revolutionized our understanding of space and time.",
])

result = rag.query("What did Einstein develop?")
print(result.answer)
Ingestion semantics
The legacy add_* ingestion helpers rebuild the full knowledge base and are planned for removal in v1.0.0. Use rebuild_texts(), rebuild_documents(), or rebuild_documents_with_triplets() for full refreshes, and use upsert_documents_by_source() / delete_documents_by_source() when a source file, page, or message changes later. See Incremental Updates for parser integration, source key design, and retry recommendations.
Getting Started
See the Getting Started guide for installation and configuration options.
Performance
| Method | MuSiQue | HotpotQA | 2WikiMultiHopQA | Average |
|---|---|---|---|---|
| Naive RAG | 55.6% | 90.8% | 73.7% | 73.4% |
| IRCoT + HippoRAG | 57.6% | 83.0% | 93.9% | 78.2% |
| HippoRAG 2 | 74.7% | 96.3% | 90.4% | 87.1% |
| Vector Graph RAG | 73.0% | 96.3% | 94.1% | 87.8% |
Historical results from before the September 2026 Jev integration.1
These benchmarks use Recall@5 and HippoRAG’s pre-extracted triplets. See Evaluation for details and the latest Jev results.
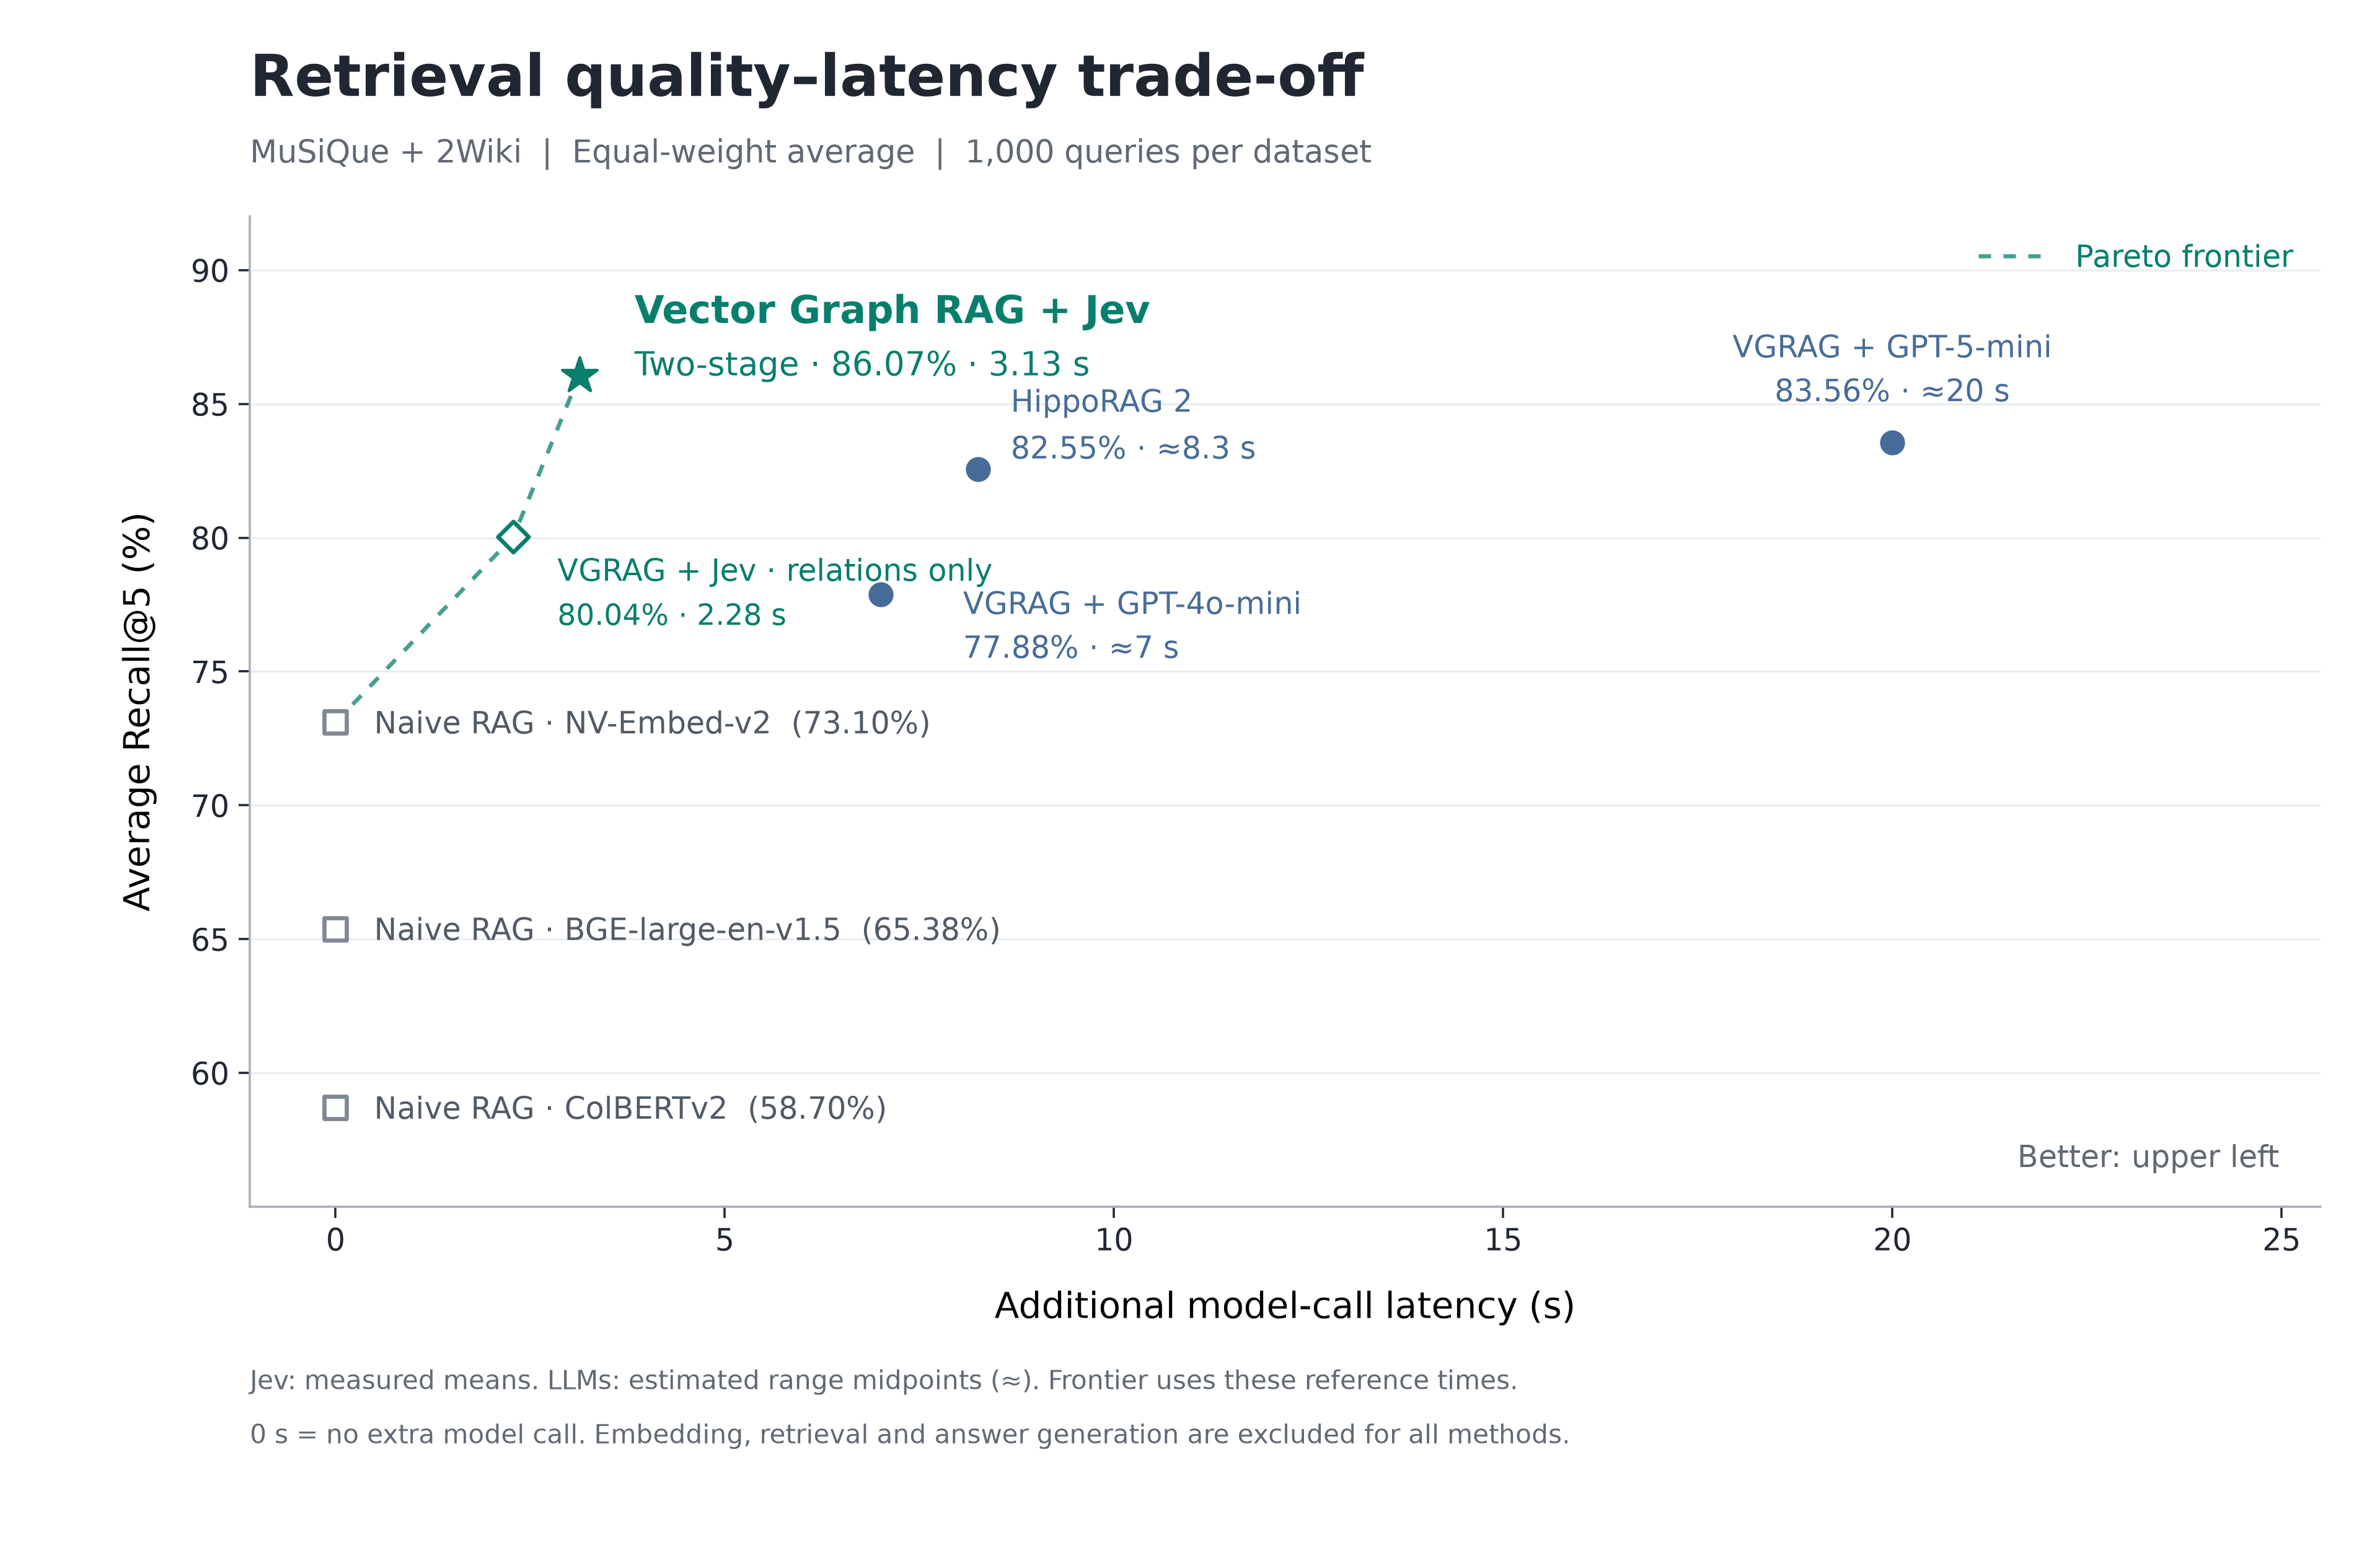
Two-stage Jev reaches the quality–latency Pareto frontier
Jev 1.14 achieves 86.61% average Recall@5 on MuSiQue and 2Wiki (1,000 questions each), the highest among the compared methods. Its estimated direct API mean is approximately 4.9 seconds. The same-query improvement over Jev 1.13 is 0.55 percentage points, reproduced on the additional 1,800 queries beyond the pilot.
With the displayed timings, this puts two-stage Jev on the quality–latency Pareto frontier. Jev 1.14 uses a calibrated direct API estimate; the other Jev, Luna and Flash points use measured API means, and HippoRAG 2 retains a reference estimate. Measurements exclude the rest of the search pipeline and differ in test conditions. This two-dataset evaluation is separate from the historical three-dataset results.
See evaluation details and configuration.
-
The HippoRAG authors resampled HotpotQA between HippoRAG and HippoRAG 2, so the historical HotpotQA results use different question samples. The original three-dataset results are retained for reference. This does not affect the new Jev comparison, which uses MuSiQue and 2Wiki only. ↩